Abstract
Articulated objects used in simulation and embodied AI are typically specified by geometry and kinematic structure, but lack the fine-grained dynamical effects that govern realistic mechanical behavior, such as frictional holding, detents, soft closing, and snap latching. Existing approaches either ignore the detailed structure of dynamics entirely, or use simple models with limited expressiveness.
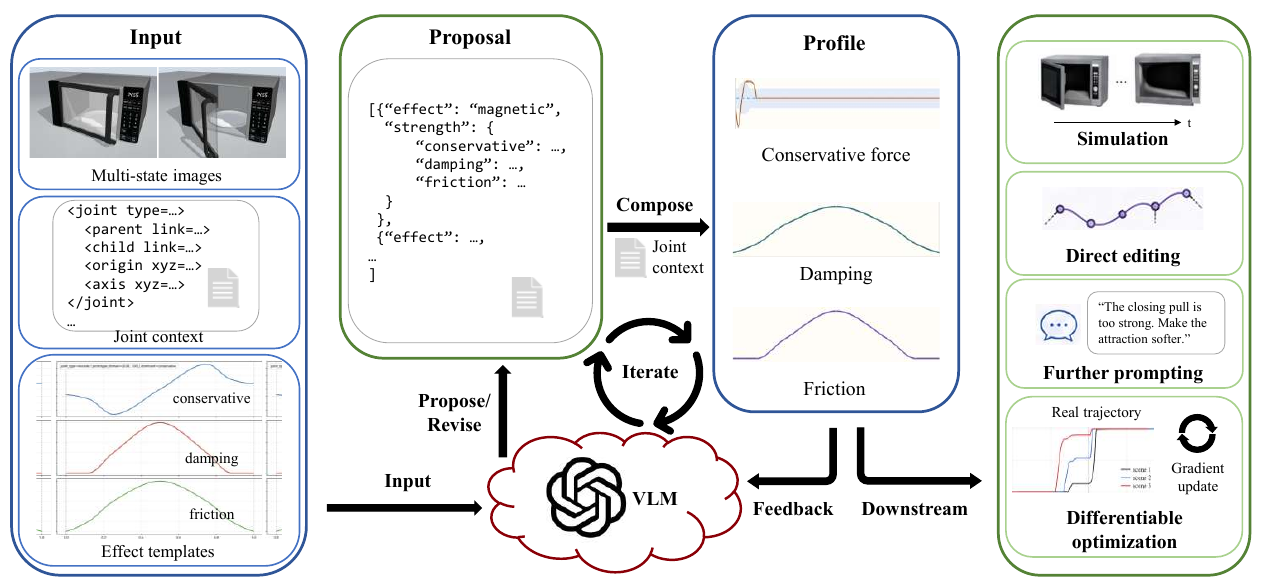
We introduce JODA, a framework for generating joint-level dynamics as a structured three-channel field over the joint degree of freedom, capturing conservative forces, dry friction, and damping. Instantiated using shape-constrained piecewise cubic interpolation (PCHIP), this formulation defines a compact, expressive, and interpretable function space that supports both direct editing and optimization-based refinement. Building on this representation, we develop an agentic generation pipeline for inferring and refining joint dynamics from multimodal inputs. Given visual observations and joint context, the pipeline uses a vision-language model to propose structured dynamical primitives, composes them into the three-channel dynamics field, and iteratively revises the proposals through diagnostic feedback.
We demonstrate that JODA enables plausible and controllable modeling of diverse joint behaviors, providing a unified interface for inference, editing, and optimization.
BibTeX
@misc{gao2026jodacomposablejointdynamics,
  title         = {JODA: Composable Joint Dynamics for Articulated Objects},
  author        = {Tianhong Gao and Cheng Yu and Yinghao Xu and Mengyu Chu},
  year          = {2026},
  eprint        = {2605.09954},
  archivePrefix = {arXiv},
  primaryClass  = {cs.RO},
  url           = {https://arxiv.org/abs/2605.09954}
}